How to Optimize for Perplexity AI Search
TL;DR: To rank in Perplexity AI, make sure PerplexityBot can crawl your pages, lead with verifiable statistics from named sources, keep content fresh, and earn corroboration from multiple independent sites. Perplexity cites live web results, so freshness and source diversity matter more than traditional link authority.
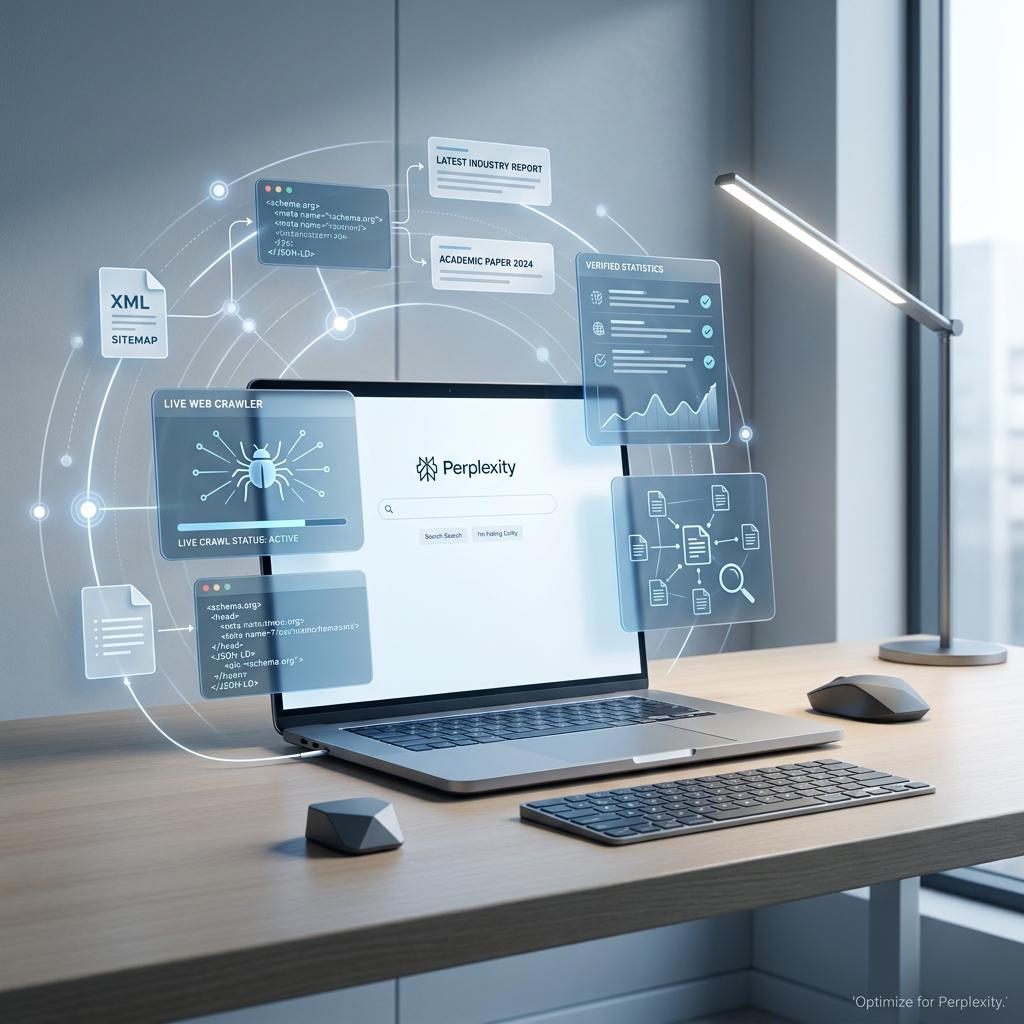
Perplexity does not rely on a pre-built index. When a user asks a question, PerplexityBot fetches live pages, extracts relevant passages, and synthesizes an answer on the spot. That single mechanical difference reshapes which pages get cited.
How Perplexity Finds and Cites Your Content
Google serves results from a periodically refreshed index, rewarding accumulated backlinks and historic engagement. Perplexity skips the index entirely. At query time it dispatches PerplexityBot to retrieve current pages, then selects those that directly answer the question.
Because the crawler must reach your site, the first gate is robots.txt. Adding the directive User-agent: PerplexityBot followed by Allow: / unlocks citation potential. Many sites that rank well on Google forget this rule, leaving Perplexity blind to their content.
Developer-focused SDK documentation about async calls or raw responses does not influence how often you get cited. Optimizing API performance will not move the needle on visibility. Crawlability and relevance do.
Why Perplexity Shows Different Sources Than Google
Google's ranking relies on a link graph where each backlink acts as a vote of confidence. Perplexity evaluates pages on how precisely they answer the query, giving little weight to overall domain authority. A niche blog with a single, well-sourced statistic can outrank a major news site if that statistic matches the user's intent.
This shift explains why ChatGPT, Gemini, and Perplexity cite different brands despite covering similar topics. Perplexity's live retrieval surfaces newer content that ChatGPT's training cut-off cannot see.
Structuring Content for Citations
Perplexity extracts self-contained passages, so lead each section with a direct answer that stands alone, then add supporting detail. For example, replace a vague intro with: "Thirty-five percent of U.S. workers who can work remotely do so full-time, according to a 2023 Pew Research Center survey of 5,000 adults."
Named sources such as "Bureau of Labor Statistics" or "2024 McKinsey analysis" signal verifiable authority. Avoid vague attributions like "studies show." Specific numbers (for example, "revenue grew 14.2% year over year") outperform ranges because they are easy to cross-reference.
Use short paragraphs and clear subheadings that mirror real user questions. Perplexity matches semantic intent rather than exact terms, so natural language that answers the question directly beats keyword stuffing.
Freshness Improves Citation Odds
Because Perplexity pulls live data, recently updated pages often outrank older, higher-authority ones. A visible "last updated" timestamp, a revised statistic, or a note about a new regulation signals currency to both the crawler and the reader.
Stat-heavy pages benefit from a quarterly review cadence; evergreen topics need updating less often. The goal is simple: any page where accuracy matters should reflect the latest information.
Source Diversity and Verification
Perplexity appears to cross-reference claims across multiple independent domains before surfacing them. A statistic cited by three unrelated reputable sites is more likely to be trusted than the same figure appearing on a single site.
Encourage partners, industry publications, and analysts to reference your data. This source proliferation boosts citation probability without traditional link-building.
Research Mode vs. Standard Search
Perplexity Pro's research mode breaks a query into sub-questions, runs separate retrievals, and synthesizes a deeper answer. This multi-step process surfaces niche sources that address narrow angles, such as "how does cobalt sourcing affect EV battery costs in Southeast Asia."
Standard mode favors concise, direct answers, while research mode rewards detailed, specialized content. Aligning your pages with specific sub-questions can capture visibility in both modes.
Key Takeaways
- Perplexity crawls the live web at query time, so fresh, crawlable pages can outrank older, high-authority sites.
- Allow PerplexityBot in robots.txt (
User-agent: PerplexityBot,Allow: /) to unlock citations. - Lead with named sources and precise statistics; avoid vague attributions.
- Corroborate claims across multiple independent domains to increase trust.
- Research mode surfaces niche, highly specific content, so structure pages to answer narrow questions.
Frequently Asked Questions
Should I use specific keywords for Perplexity, or just write naturally?
Natural, specific phrasing that fully answers a question works better than keyword stuffing, because Perplexity matches semantic intent.
How do I make my website crawlable by PerplexityBot?
Include the directive User-agent: PerplexityBot with Allow: / in robots.txt, and make sure no server-level blocks prevent access.
What kind of content does Perplexity AI prefer?
Content that leads with direct answers, cites named authorities, provides exact figures, and is regularly refreshed tends to be cited more often.
Is Perplexity AI different from Google or ChatGPT for SEO purposes?
Yes. Perplexity retrieves live web results and values source diversity and freshness, while Google leans on link-based authority and ChatGPT relies on its training data.
Can I track how often my content gets cited in Perplexity?
Yes. Authority Radar's guide on monitoring brand mentions in Perplexity explains measurement, and the Authority Radar platform provides ongoing citation tracking.
Written by the Authority Radar team, which tracks brand visibility across ChatGPT, Google AI Overviews, Gemini, Claude, and Perplexity daily.