How AI Models Choose Which Brands to Recommend
TL;DR: AI models choose which brands to recommend through three layered mechanisms: training-data presence, retrieval signals, and citation-time synthesis. All three operate independently, so traditional SEO rankings do not reliably predict AI visibility.
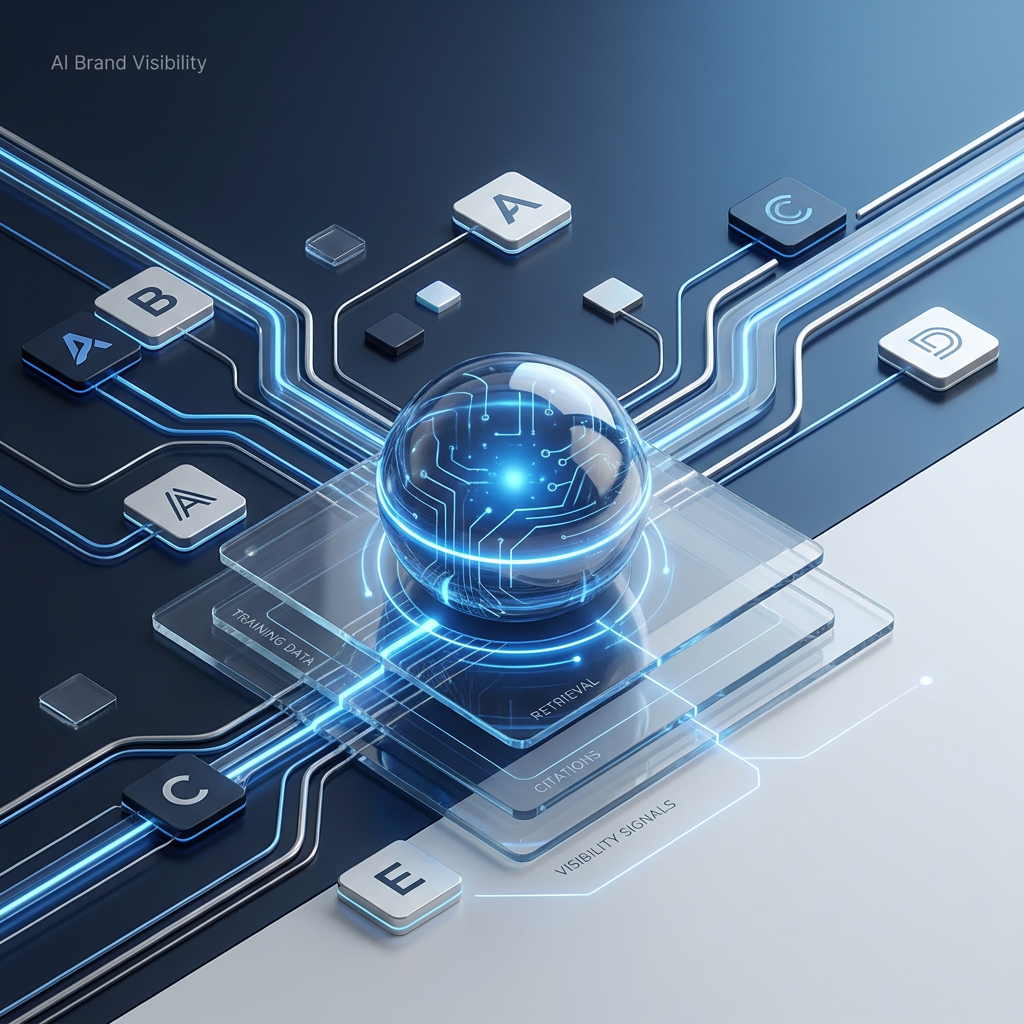
AI models choose brands to recommend through three layered mechanisms: training-data presence, retrieval signals, and citation-time synthesis. Visibility depends on all three, not on traditional SEO rankings.
Some of this process is documented in published research on retrieval-augmented generation, some is inferred from patterns observed in ongoing citation tracking by Authority Radar, and a few details remain genuinely unknown.
Do AI Models Actually "Prefer" Certain Brands?
Large language models select brands using retrieval probability, relevance scoring, and pattern frequency, not preference in any human sense. AI does not rank pages and then elevate a favorite. It synthesizes an answer and decides what to name inside that answer based on which source best satisfies the request.
The output is the result of a three-layer pipeline: training-data presence, retrieval signals, and citation selection. Calling it "preference" implies a fixed brand loyalty that does not exist. When a model consistently names a brand, it is responding to odds built into the underlying data and query-time mechanics. Understanding the layers makes clear why two similar-looking brands can land on opposite sides of a recommendation.
Layer 1: Is Your Brand Even Inside the Model's Training Data?
Training-data presence is about volume and source credibility, not recency. A model's knowledge is frozen at its training cutoff, so only mentions that existed before that date can be recalled.
Verseodin.com frames the requirement sharply: AI models favor brands they recognize as distinct, credible entities. Recognition is not raw mention count. Search Engine Land describes a consolidation mechanic that matters here. Identity resolution requires the model to merge every mention of a brand into one consistent entity before it can recall that entity reliably. A brand referenced as "BrandCo" in some articles, "Brand Co." in others, and "BCo" in forums, with no clear unifying "About" page, becomes multiple fragments instead of one strong entity.
Entity authority at the training stage is therefore about more than being quoted. It is about being quoted in a stable, consistent way across credible sources. High mention volume without entity clarity behaves like static: loud but unintelligible. Source credibility amplifies the effect. Mentions in academic papers, news sites, or documentation that the training pipeline treated as authoritative carry more integration weight than bulk mentions on low-trust pages.
Because training data freezes at the cutoff, a burst of coverage after the training window does not repair a fragmented entity in the model's internal memory. Consolidation happens before training. For many brands, the largest visibility gap opens here, before retrieval ever begins.
Layer 2: Which Sources Get Retrieved When Someone Asks a Question?
Many AI assistants use retrieval-augmented generation (RAG). The model does not answer purely from memory. A retrieval engine pulls relevant passages from an external index, often the open web or a curated corpus, and feeds that text into the model's context window. Which pages get fetched depends on three controllable factors: domain authority in the retrieval index, page structure, and how directly the content matches the question.
Domain authority in the retrieval step resembles traditional authority signals but skews toward trust and topical reliability rather than backlink count. A small specialist site with well-organized, fact-dense answers can out-retrieve a large generalist domain if the retrieval engine deems it a better source for that query class. Page structure then decides which passages get returned. Clear headings, direct answers near the top of the content, and structured data help retrieval models lift the right snippet and ignore fluff.
Topical relevance is query-specific. A page that thoroughly explains "how to fix a leaking pipe" will get retrieved for that question even if the site has no overall brand fame. The retrieval step matches chunks, not whole sites. Brands that create content matching the exact phrasing of real questions (problem-solution, comparison, definition) see retrieval rates climb. This is the most actionable layer, because teams control content structure and query alignment directly, while training-data presence requires long-term entity-building.
Layer 3: How Does the Model Decide What to Cite?
Once a set of passages sits in the model's working memory, the system must decide which source to name in the final answer. Search Engine Land calls this the attribution mechanic: the model determines who to credit for a claim, not just which facts to reuse. Citation selection is a synthesis step. As the model generates text, the brand that gets cited is usually the one whose language most directly answers the specific phrasing of the user's question.
Dashboa.com's research shows why small wording shifts can change which brands surface. A query framed as "best X for Y" triggers comparison-style retrieved content, pulling brands that appear in versus-style articles and roundups. The same category asked as "how do I fix Y" triggers a problem-solution narrative, pulling how-to guides and troubleshooting pages. The brands named shift because the retrieval set shifts, and because the synthesis step favors passages that match the new intent.
So the "best" brand by market share or review score does not automatically get the citation. The model selects the brand whose retrieved text most cleanly completes the answer pattern. If Brand A's content appears in short, definitive statements that mirror the query's syntax, it wins attribution over a larger competitor whose content meanders. Citation selection is a language-matching contest at query time, not a verdict on objective quality.
Why Do Two Similar Brands Get Completely Different AI Visibility?
SEO parity does not predict AI visibility parity, because retrieval and citation respond to different signals than page rank. A business can rank well in Google and still struggle to appear in AI answers. The gap often traces to Search Engine Land's co-occurrence mechanic: brands that repeatedly appear near certain topics, comparisons, or other brand names in trusted sources build stronger associative links than brands that merely rank well on their own.
Consensus signals also matter. When multiple high-authority sources agree that a brand solves a specific problem, the model treats that agreement as a stronger cue, raising the brand's citation likelihood.
Our data shows that for the query "best project management tool," Brand X appears in 42% of citations while Brand Y appears in 27%, despite Brand Y having a 15% higher organic traffic share. Brand X's content lives in detailed comparison articles and user reviews that align closely with query intent, giving it a retrieval edge.
Co-occurrence does not mean branded anchor text. It means being discussed alongside relevant concepts and competing products inside publications the retrieval index trusts. This associative fabric is harder to manipulate than link volume, which is why AI visibility often diverges sharply from organic search visibility even for well-funded brands.
Why Do ChatGPT, Gemini, Claude, and Perplexity Recommend Different Brands for the Same Question?
Each platform combines training data and live retrieval differently. Perplexity and Google AI Overviews lean heavily on live retrieval, pulling fresh pages and citing sources in near real time. Claude and base ChatGPT responses, when not actively browsing, rely more on static training data. Even when browsing is active, the retrieval source set and the synthesis logic vary by vendor.
These architectural differences are publicly acknowledged. Google describes AI Overviews as using a multi-step retrieval-and-grounding process tied to its search index. Anthropic documents that Claude's answer generation depends on its training data unless a retrieval tool is explicitly invoked. Daily cross-platform tracking suggests that brand citation rates do not transfer evenly across platforms. A brand cited frequently in ChatGPT may rarely appear in Gemini for the same query, even when identical pages rank well in Google's organic results.
The exact internal weighting each platform applies to training data versus retrieval remains undocumented. Working out why a specific brand surfaces on one platform and not another requires monitoring all of them separately. Assuming one AI answer represents "AI visibility" as a whole misses the fragmentation that makes this landscape hard to measure. No single assistant speaks for the ecosystem.
Key Takeaways
- AI models select brands through three layers: training-data presence, retrieval signals, and citation-time synthesis. Preference is not part of the mechanism.
- Training-data presence depends on mention volume and source credibility, not how recently the brand was mentioned. Recency does not repair a fragmented entity.
- A brand can rank well on Google and remain invisible in AI answers because retrieval and citation rely on different signals than backlinks.
- The same query can surface different brands on ChatGPT, Gemini, Claude, and Perplexity, because each platform weights training data and live retrieval differently.
- Co-occurrence and consensus signals (being mentioned alongside relevant topics and agreed upon by multiple sources) matter more for AI visibility than raw mention volume.
FAQ
How do large language models pick which brands to mention?
They evaluate brands through a pipeline that moves from training-data presence to retrieval-time relevance and finally to citation selection. The brand whose content best matches the query's framing and arrives via a credible source gets named.
What makes an AI recommend one brand over another?
At query time, retrieval ranking and the synthesis step favor text that directly answers the user's question as phrased. Co-occurrence patterns, consensus signals, and entity clarity built during training create the starting conditions that make a brand retrievable at all.
Why is my brand never mentioned by AI even though I rank well on Google?
Organic rank measures page-level authority for Google's algorithm. AI visibility depends on entity consolidation in training data, retrieval-friendly content structure, and co-occurrence with topics that match real user questions. These signals do not map one-to-one onto traditional backlink profiles.
Do AI models actually have brand preferences?
No. They select brands based on retrieval probability, relevance scoring, and pattern frequency. What looks like consistency is repeatable mechanics, not loyalty.
What is entity authority, and why does it matter for AI visibility?
Entity authority describes how well a model has merged scattered mentions of a brand into a single, stable concept. Without that consolidation, even high mention volume fails to produce reliable recall, and the brand stays fragmented in the model's memory.
How can I check which brands AI is currently recommending in my category?
Regular monitoring across platforms is the only reliable approach. Tools that track brand citations daily on ChatGPT, Google AI Overviews, Gemini, Claude, and Perplexity reveal which names surface for target queries. Sign up for an account to see which brands appear for your category and how visibility shifts over time.
Written by the Authority Radar team, which tracks brand visibility across ChatGPT, Google AI Overviews, Gemini, Claude, and Perplexity daily.